THE QUESTRA JOURNAL
Ideas for the work behind the research.
Notes on survey programming, testing, and the systems that help research teams move with more confidence.
Read by subject
MORE TO EXPLORE
Research, without the busywork.
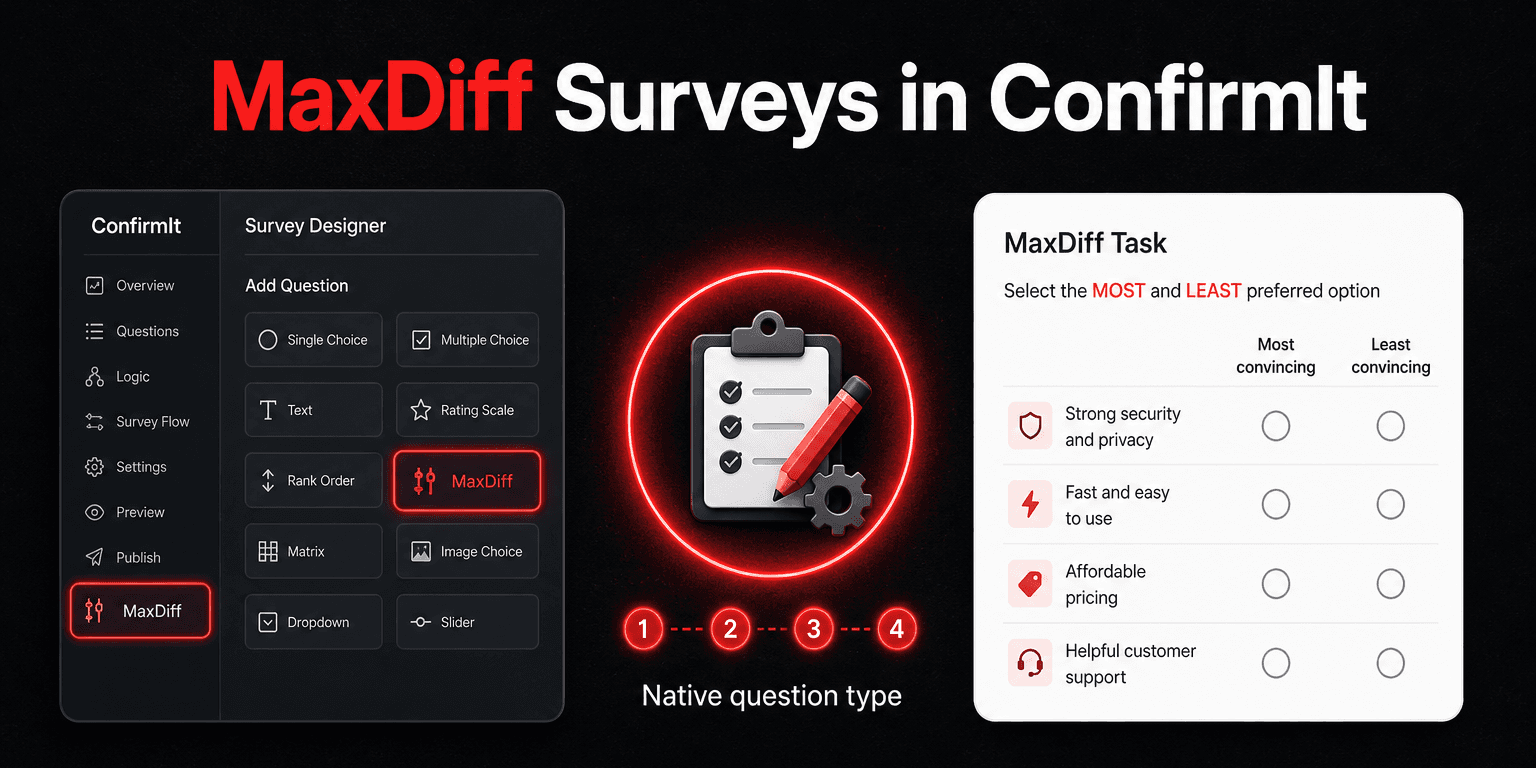
ConfirmIt MaxDiff Survey Programming Guide
Step-by-step ConfirmIt MaxDiff setup — native question type, page design, and item labels.
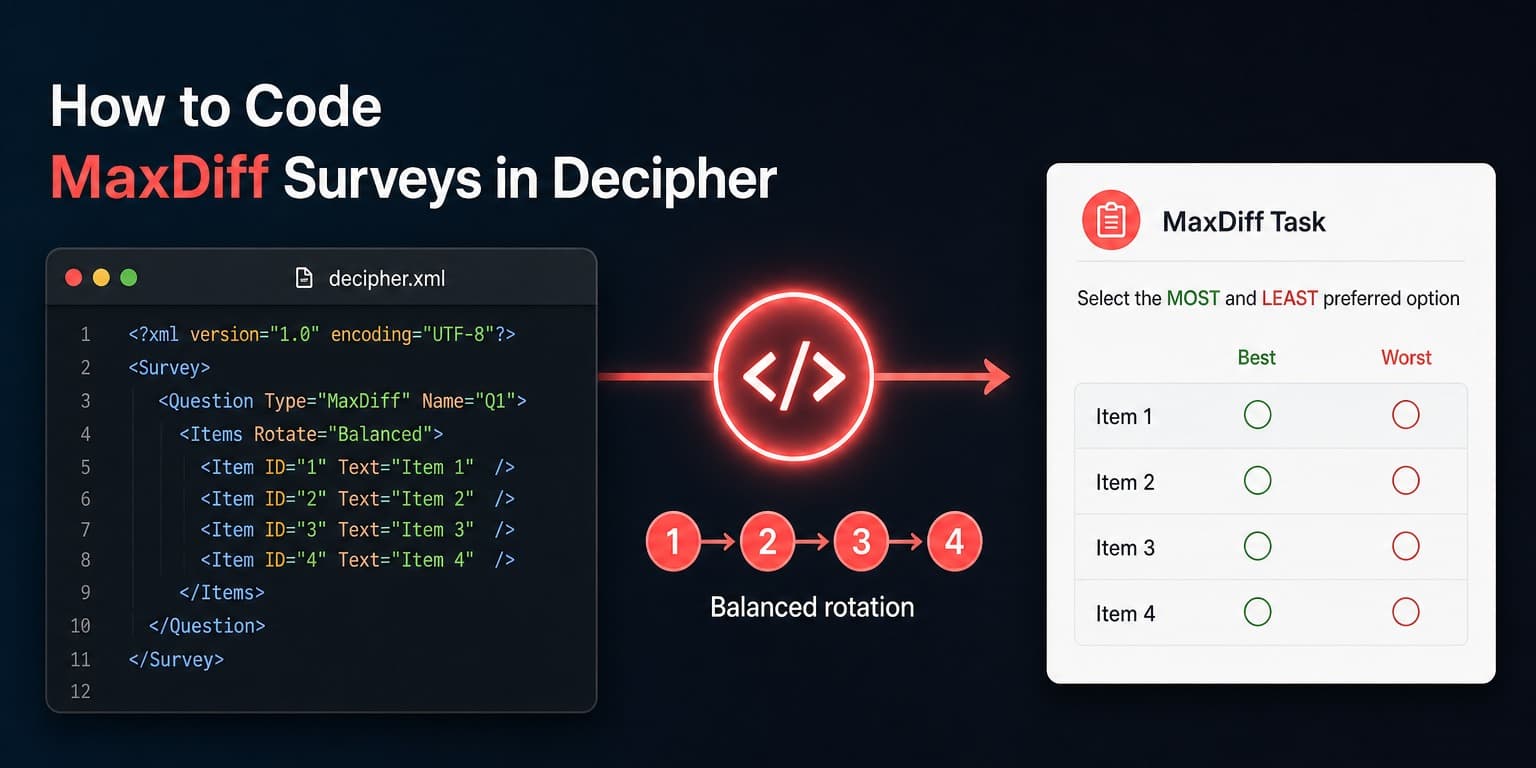
Decipher MaxDiff Survey Programming Guide
Step-by-step Decipher MaxDiff programming with balanced assignment, loop XML, Python exec filtering, and copy-ready Indices Method code.
Human-in-the-Loop Is Not Optional in AI Survey Programming
AI that programs surveys without human oversight is a liability. Here's why the testing phase — not just the build — is where human involvement matters most.
Multi-Platform Survey Programming Without the Switching Tax
Your team programs in Decipher one week and Qualtrics the next. A platform-agnostic approach eliminates the switching tax — program the questionnaire once, deploy to any survey platform.
Three Ways to Put an AI on Trial
Most AI tools in market research come with self-published benchmarks and no independent evaluation. Here are three frameworks for actually testing them.
AI Fatigue Is Hitting Your Workday the Same Way Tip Fatigue Hit Your Wallet
Not every AI use case earns its place. Here's how to spot the ones causing burnout and focus on the ones that actually make the job easier.
The Rise of Research Operations (and Why AI Makes It Possible)
Research operations is becoming its own discipline, and AI is why. Here's what it covers, why it matters now, and how to get started.
The Forgotten Middle: Why Survey Programming Is the Biggest Bottleneck in Research
The industry obsesses over AI for analysis and design. But the real time sink — translating questionnaires into programmed surveys — is the part nobody's fixing.
Automated Survey Link Testing: The QA Gap Nobody Talks About
Survey link testing is one of the most tedious, error-prone tasks in research — and one of the most consequential. Here's why automated testing is overdue and what it looks like.

How We Measure Survey Programming Efficacy (Without Guessing)
AI survey programming needs evaluation that matches how researchers judge quality: against real programmed surveys, across content and logic, with platform-aware detail and a shared respondent model—not a vibes check.
Self-Healing Programming Loops: QA That Runs During the Build
We're shipping self-healing programming loops — questionnaire comparison, diagnostics repair, and push-error remediation — inside initial survey programming, based on what worked in the post-programming agent.
The Curse of Dimensionality in Survey Testing: Why Breadth-First Search Fails and How Combinatorial Covering Arrays Solve It
How naive breadth-first survey crawling collides with quadrillions of paths, and how dynamic pairwise covering arrays compress state spaces from millions of years to two minutes.

The MaxDiff Design Gap: Why Your Survey Software Doesn't Use a "Perfect" Experimental Design (and Why That's Okay)
BIBD is the gold standard for MaxDiff design — but almost nobody uses it. Here's what your survey software actually does, where the gaps are, and what researchers should pay attention to.
The Researcher's Dilemma: When 'Do More With Less' Meets 'Maintain Quality'
Research teams face an impossible ask: increase throughput, cut costs, and keep quality flawless. The way out isn't working harder — it's automating the right things.
What 'Agentic AI' Actually Means for Survey Research — Beyond the Buzzword
Agentic AI is everywhere in research tech marketing. Here's what it concretely means for survey workflows, how it differs from chatbots and copilots, and where human oversight still matters.